

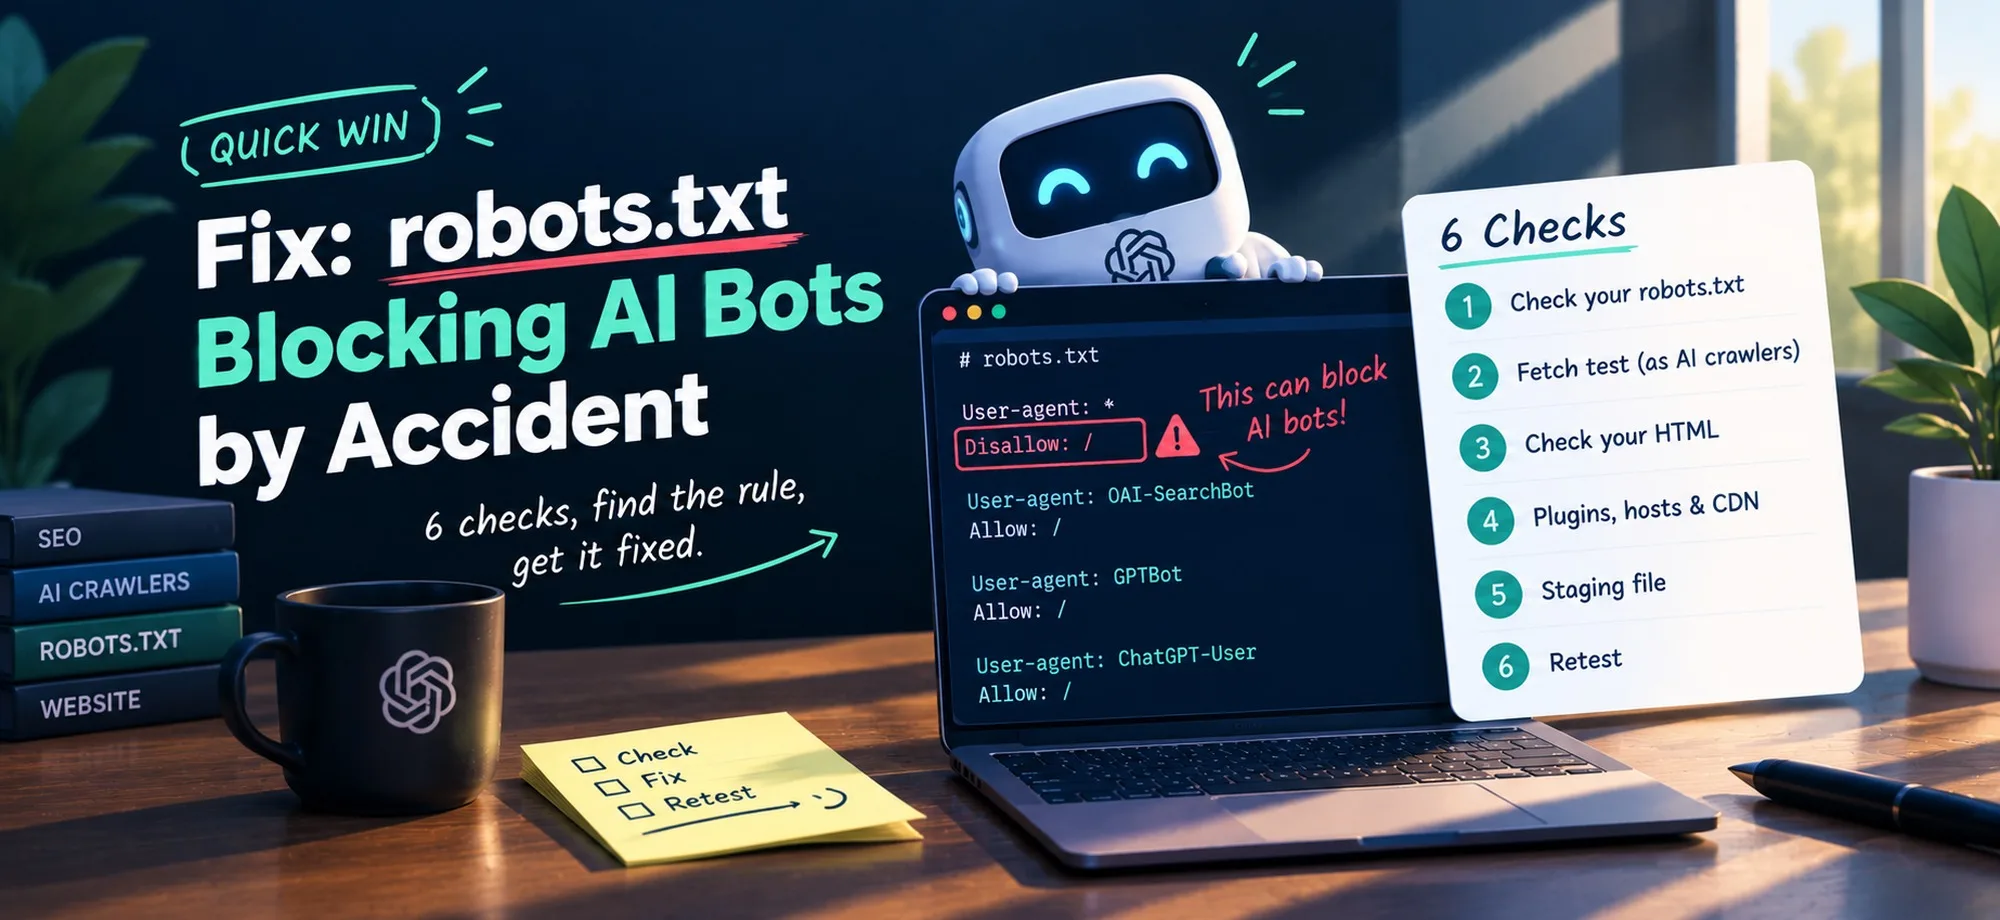
If AI crawlers cannot read your site, the cause is often one line in a file you may not have touched in months. A robots.txt that blocks AI bots by accident is common, easy to miss, and quick to fix once you know where to look. Work through the checks below in order. They run from the most common cause to the ones that need access to settings or deployments.
1. Open the live robots.txt
Visit yourdomain.com/robots.txt in a browser and read what comes back. Do not trust the copy in your code repository. A plugin, a host or a build step can change the file that visitors, and crawlers, actually receive.
A healthy file is plain text made of groups. Each group starts with a User-agent line and is followed by Allow or Disallow rules. If you are unsure what the file does compared with your sitemap or an llms.txt file, this guide to robots.txt, sitemap.xml and llms.txt covers the differences.
2. Look for a wildcard disallow
This is the most common cause. It looks like this:
User-agent: *
Disallow: /
The star means "every crawler", and a single slash means "the whole site". Any crawler without its own group in the file follows this one, so AI bots and Googlebot are both locked out.
To fix it, empty the Disallow line so it allows everything:
User-agent: *
Disallow:
If you only meant to keep one area private, block that path instead of the whole site:
User-agent: *
Disallow: /admin/
3. Look for AI bot groups you did not write
Even with the wildcard fixed, a crawler with its own group follows that group and ignores the wildcard. Search the file for names such as GPTBot, ClaudeBot and CCBot:
User-agent: GPTBot
Disallow: /
A block like this may have been added by a plugin, a template or a past decision you forgot. Confirm every rule is deliberate. The full set of crawler names is listed in the AI crawler list for robots.txt, and the steps to flip a single crawler are in how to allow or block GPTBot in robots.txt. Keep any block you chose on purpose.
4. Check plugins, hosts and CDN settings
Security plugins, SEO plugins, hosts and CDNs can edit robots.txt or block AI bots through a setting. Look for options named like "Block AI bots", "AI crawler blocking", "managed robots.txt" or a virtual robots.txt editor.
Some of these blocks happen at the network level, so they never appear in your robots.txt. If the file looks clean but crawlers still fail, this is where to look next.
5. Check whether a staging file went live
A restrictive robots.txt copied from a staging site is a classic cause after a launch or a migration. Staging sites usually carry the same blanket rule from step 2. Compare the production file with the one you intended to publish, and replace it if it matches staging.
6. Retest after each change
Change one thing at a time, then retest. Run your domain through the AI crawler checker to see which crawlers are still blocked. Then confirm that ChatGPT can reach you using how to check if ChatGPT can see your site.
Decide crawler by crawler
Fixing an accidental block does not mean you must allow every AI crawler. Training bots, search bots and user-request bots have different effects, so decide for each one. If you are worried about search visibility, read whether blocking GPTBot hurts your Google ranking before you change anything you intended.
Fixing robots.txt removes a barrier. It does not guarantee that any AI tool will cite your site.
Comments
No comments yet — be the first.